AI Data Labeling Explained: Types, Steps, and Best Practices
Learn how labeled data helps machine learning models make better predictions.
What Is AI Data Labeling?
AI data labeling means adding useful tags to raw data. The data may include images, text, audio, or video. These tags tell a machine learning model what each item shows or means.
For example, a team may mark cars in street images. It may also tag a review as positive or negative. A speech file could carry a written transcript. These labels help a model spot patterns during training.
So, what is data labeling for AI? It is the step that turns raw examples into training data. In many projects, people review each item and assign the right label.
Data labeling is vital for supervised learning. This learning method uses labeled examples to guide model training. The labels act as the known answers that the model tries to predict.
Labels also help define ground truth. Ground truth means the best available answer for an example. Teams use it to test model results and measure accuracy.
How the Data Labeling Process Works
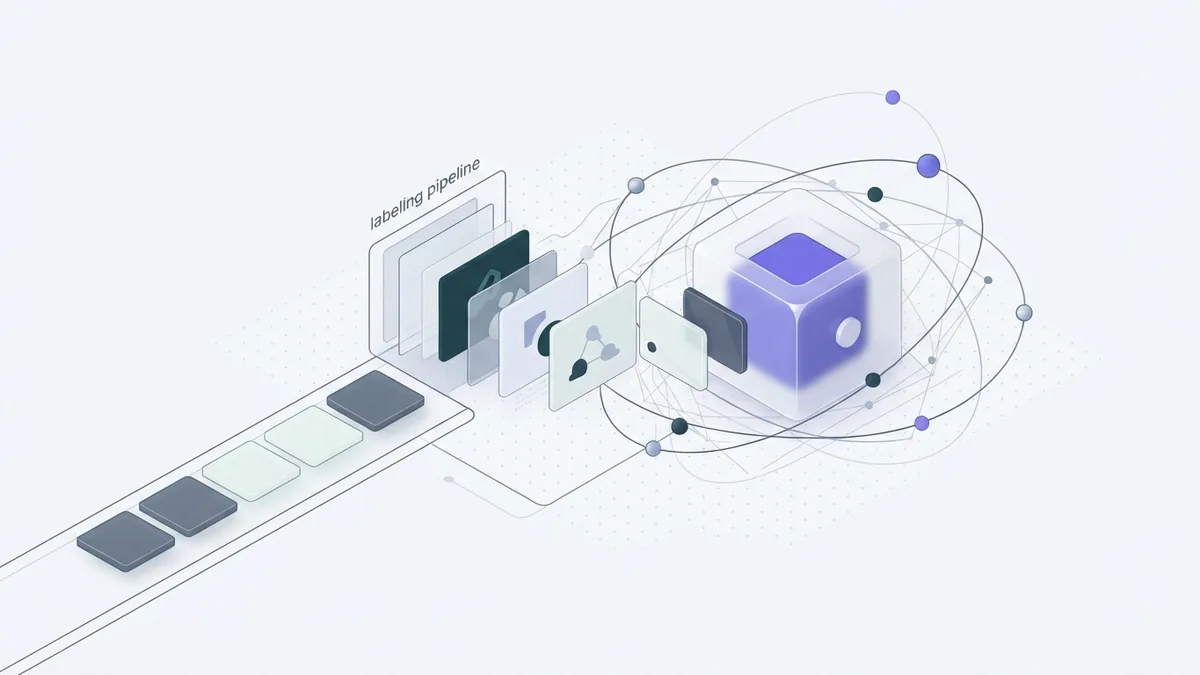
Data labeling starts with a clear goal. A team first decides what the model must detect, sort, or explain. That goal shapes the label rules and review method.
Next, the team gathers and cleans the source data. This stage may remove duplicate files, blurred images, or broken audio. It may also split data into training, validation, and test sets.
Then, labelers add tags through a chosen tool. A label might be a class, a box, a mask, a transcript, or a score. Each label type suits a different machine learning task.
- Set the label rules. Define each label with plain examples.
- Prepare the data. Remove poor files and protect private details.
- Label a small sample. Use it to find unclear cases early.
- Label the full set. Give workers the same rules and tools.
- Review the work. Check samples and resolve disagreements.
- Export the dataset. Store labels beside the correct source files.
Quality checks should run during the work. A second labeler can review a sample. A lead reviewer can settle hard cases. This human-in-the-loop approach helps catch errors before model training.
Teams may also use automated data labeling. A small trained model can suggest labels for new items. People should still check those suggestions, especially for rare or costly mistakes.
Google's definition of supervised learning also links model learning to labeled examples. This makes the label set part of the model's learning signal.
Common Types of AI Data Labeling
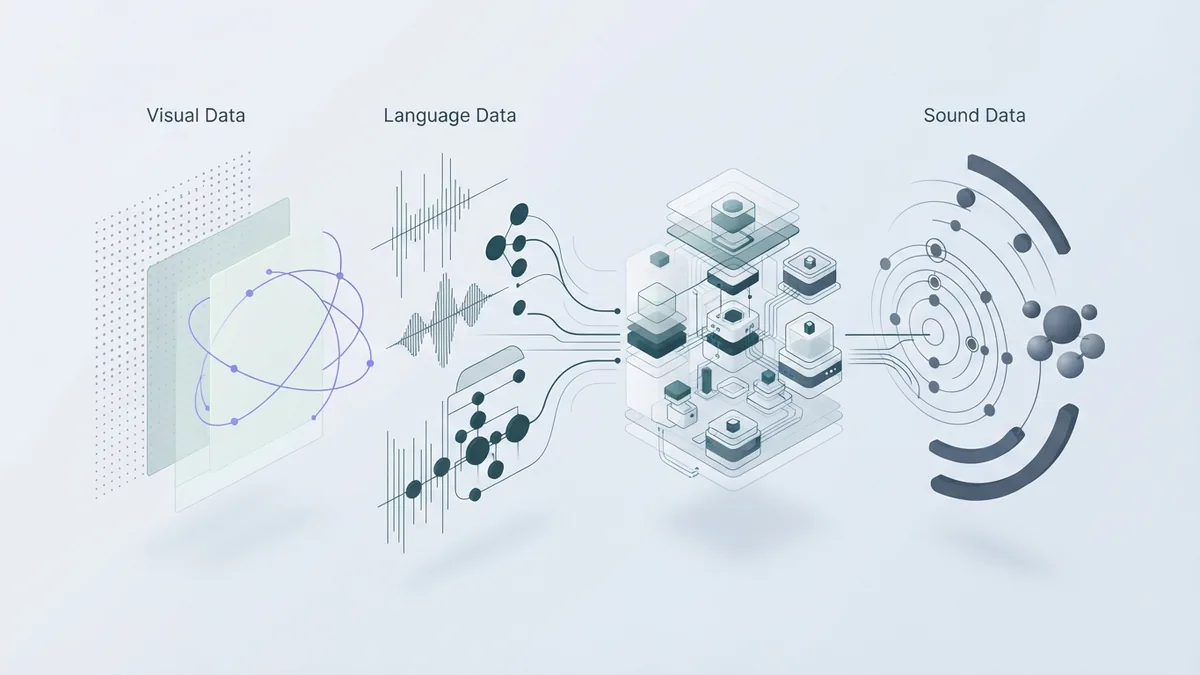
The right label type depends on the data and the task. Computer vision needs labels tied to pixels or objects. Text and audio need labels tied to meaning, order, or sound.
Computer vision labeling
Image labeling can assign one class to a whole image. For example, an image may show a healthy plant or a diseased plant. This method is called image classification.
Object detection adds boxes around separate items. A road image may contain boxes for cars, bikes, and signs. Image segmentation marks the exact pixels linked to each object.
Natural language processing labeling
Natural language processing helps software work with human language. Text labels may show topic, mood, intent, or risk. A support message could receive a billing or delivery tag.
Named entity labeling marks items such as names, places, or dates. Text ranking can also show which answer best matches a question. These labels support search, chat tools, and document sorting.
Audio and video labeling
Audio labeling may include speech transcripts, speaker turns, or sound types. A dataset could mark alarms, traffic noise, or spoken commands. Clear time marks help models find sounds within long files.
Video labeling often combines images, motion, and time. Reviewers may track an object across frames. They may also mark actions, events, or scene changes.
| Data type | Common label | Example use |
|---|---|---|
| Image | Class or object box | Find road hazards |
| Text | Topic or intent | Sort support requests |
| Audio | Transcript or sound class | Recognize spoken commands |
| Video | Tracked object or event | Review movement patterns |
Best Practices for Better Labels
Good labels start with narrow rules. Each label needs a short meaning and clear examples. Rules should also cover edge cases, such as partly hidden objects or mixed emotions.
Use the same rule for every item. A label that changes by worker will weaken the dataset. Small pilot tests can reveal gaps before the full job begins.
- Write rules with positive and negative examples.
- Keep labels separate when they answer different questions.
- Use a review sample from every batch.
- Track agreement between two or more labelers.
- Record why a hard case received its label.
- Keep test data apart from training data.
Label agreement is a useful quality signal. If two trained workers often disagree, the rule may need work. The team should review the cause instead of forcing a quick choice.
Balance matters too. A dataset with 95 percent one class may hide weak results. Add enough examples from less common classes. This helps the model learn cases that matter most.
Protect data during the full workflow. Remove private details when possible. Limit access to source files and keep a record of label changes.
Key Challenges in Data Labeling
Labeling can take more time than teams expect. A simple image class may take seconds. A detailed pixel mask can take many minutes. Large datasets can turn that gap into a major cost.
Human error is another risk. People may miss small objects, read unclear speech, or apply rules in different ways. Fatigue can raise error rates during long shifts.
Some data also needs expert review. Medical images, legal text, and technical recordings need skilled labelers. Expert time costs more, yet poor labels can cost more later.
- Cost: More detail usually needs more worker time.
- Time: Complex labels slow each review.
- Bias: Label rules may reflect narrow views.
- Privacy: Raw data may contain personal details.
- Drift: New data may not match old label rules.
Automation can lower the workload, but it does not remove the need for checks. A weak automated label can spread the same mistake across thousands of files. Human review remains vital for rare cases and safety tasks.
Teams should plan for label updates after launch. New products, slang, scenes, or sounds may need new classes. A fixed label set can lose value as real-world data changes.
Why Data Labeling Matters in Machine Learning
Labels give a model a target during training. The model compares its guess with the known label. It then adjusts its internal settings to reduce the gap.
Better labels often lead to better predictions. They help the model learn useful patterns instead of noise. They also make test scores more meaningful.
This link matters because accuracy is only as good as the test answers. If the ground truth contains many mistakes, a model may look better or worse than it is. Reliable labels support fair model checks.
Label quality also affects business results. A vision model may miss a damaged product. A text model may send an urgent request to the wrong team. Better labels can reduce such errors and improve user trust.
Data labeling is not just a setup task. It supports model training, testing, and later updates. Teams that treat it as core work can spot weak data before it harms the final system.
The NIST AI Risk Management Framework stresses the need to test and manage AI risks. Strong labels help teams check those risks with clearer evidence.
A practical way to judge label quality
Start with a small set that experts agree on. Compare worker labels with that reference set. Then review errors by class, worker, and data source.
Do not chase one score alone. Check rare classes, hard cases, and changes over time. A strong dataset supports the task the model must perform in the real world.
Frequently asked questions
- What is AI data labeling?
- AI data labeling adds meaningful tags to raw data. These tags help a machine learning model learn patterns and make predictions.
- What is data labeling in AI used for?
- It creates labeled examples for supervised learning. Teams also use labels to define ground truth and test model performance.
- What are the main types of data labeling?
- Common types include image classes, object boxes, image masks, text intent tags, speech transcripts, and video event labels.
- Why is data labeling important for machine learning?
- Labels give the model a target during training. Better labels can improve accuracy and make test results more reliable.
- What are the biggest challenges in AI data labeling?
- The main challenges are human error, high cost, slow review work, privacy risks, and unclear label rules.
- Can AI automate data labeling?
- Yes. A model can suggest labels for new data. People should review those suggestions, especially for rare or high-risk cases.
Related reading
Use AI in Real Estate to Work Smarter
See how AI can save time, find leads, and improve client service.
Learn AI and Machine Learning — Build Skills That Last
Build your AI skills with a simple path from Python to real projects.
Build AI Agents from Scratch (Beginner Path)
Build your first AI agent with simple tools, clear steps, and beginner-friendly tips.